How to run & interpret repeated measures T-test in SPSS?

Paired sample t-test

A paired sample t-test is used to compare two means where you have two samples in which observations in one sample can be paired with observations in the other sample. Instances, where this might occur, are:

  • After and before observations on the same subjects (e.g. students’ symptomatic test results before and after an appropriate module or course).
  • An association of two different methods of measurement or two different treatments where the computations/methods are applied to the same subjects.

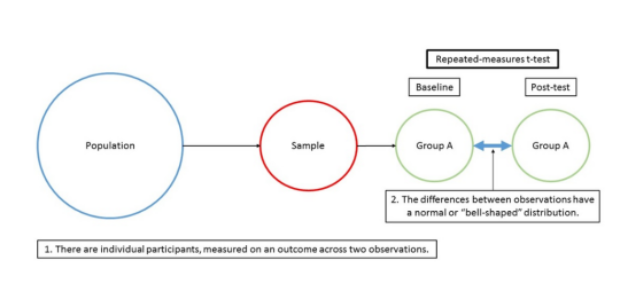
The flow depicts the use of a repeated-measures t-test. There is only one association being inspected at two within-subjects observations or two-time points for a continuous outcome. The assumption of normality of separation records has been met. A repeated-measures t-test is used to assess the change in a continuous outcome at two within-subjects observations or two-time points
 SPSS help

 ASSUMPTIONS:

The paired sample t-test makes some assumptions. Although t-tests are quite robust, it is a reliable practice to evaluate the degree of deviation from certain assumptions to estimate the essence of the results. The paired sample t-test has four  assumptions:

  • The dependent variable should be continuous (interval/ratio).
  • The observations are independent of one another.
  • The dependent variable should be  normally distributed.
  • There should be no notable outliers in the variances among the two related groups.

Level of Measurement

In paired sample t-test the sample data should be numeric and continuous, as it should be normally distributed. Continuous data can take on any value within a range . The contrast of constant data is discrete data, which can only take on a few value .Occasionally, discrete data can be used to approximate a continuous scale example likert scale.

Independence

Independence is usually not testable but can be reasonably assumed if the data collection process was random without replacement. Example, it is good enough to assume that the participating patients are independent of one another.

 Normality

To test the presumption of normality, a variety of methods are available.  Real-world data are rarely perfectly normal, so this assumption can be regarded as fairly met if the state looks nearly symmetric and bell-shaped.

Example

A group of Sports students (n = 20) is picked from the population to examine whether a 19-week preparation program improves its standing high jump performance. This method is used to test whether this training increases performance, the students are tested for their long jump performance before they begin a training program and then at the end of the programme (i.e., the dependent variable is “standing high jump performance”, and the two similar groups are the standing high jump values “before” and “after” the 19-week training program).

Test Procedure in SPSS Statistics

The six steps below explain to you how to analyze your data using a dependent t-test in SPSS Statistics Assumptions, should not be outraged. Following the six steps, the interpretation of the results is also commuted depending on the data analysis.

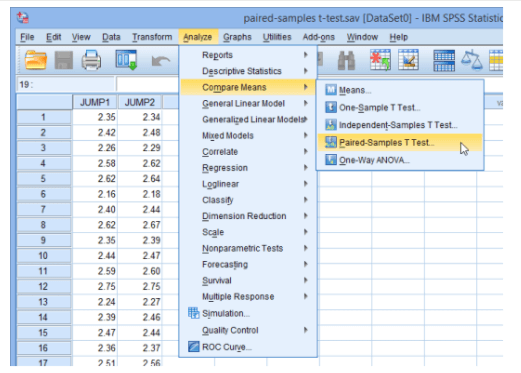
  1. Click Analyze 

> Compare Means

 > Paired-Samples T Test… on the top menu, 
spss consultant

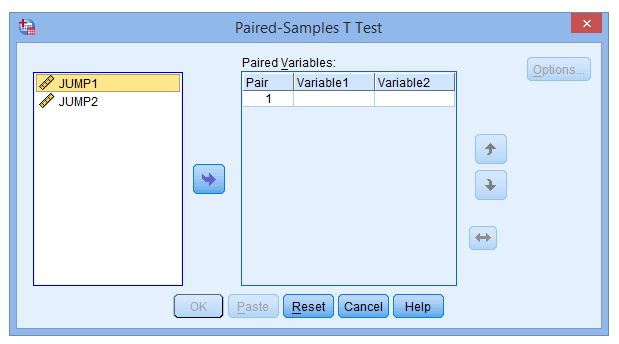
  1. You will be shown with the Paired-Samples T Test dialogue box, as explained here:
 spss help services

  1. Assign the variables JUMP1 and JUMP2 within the paired box. There are two methods to do this: 

(1) click on both variables whilst bringing down the shift key and then pressing the button

 (2) drag-and-drop each variable individually into the boxes.
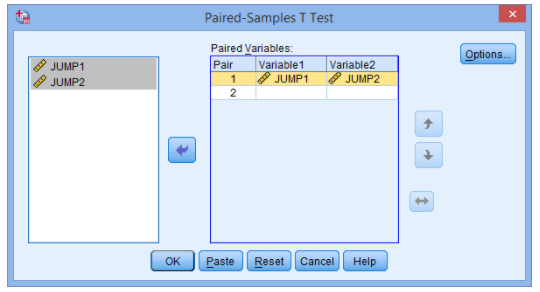
T test help

  1. If you want to adjust the confidence level limits or eliminate cases, click on the options button. After performing the Paired-Samples T-Test: Options dialogue box, as explained here:
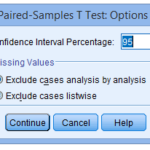
 

5.Click the continue button. You will be returned to the Paired-Samples T Test dialogue box

6.Click the OK button.

INTERPRETATIONS:

PSS Statistics generates three tables in the Output Viewer under the title “T-Test”,look at two tables: the Paired Samples Statistics table and the Paired Samples Test table.

Paired Sample Statistics Table

The initial table, titled Paired Samples Statistics, is where SPSS Statistics has generated detailed statistics for your variables. You could use the results here to describe the features of the first and second jumps in the write up
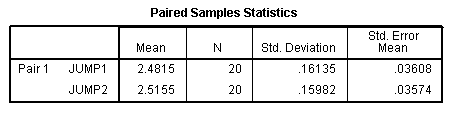
 paired sample statistics

 Paired Samples Test Table

The Paired Samples Test table is wherever the results of the dependent t-test are presented. A lot of information is displayed here and it is essential to identify that this information refers to the variations between the two jumps.  paired sample test
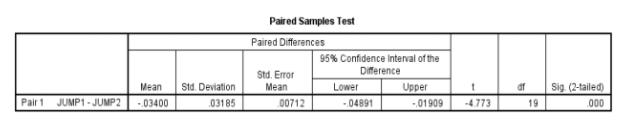
 When drafting up the results of your t-test you need to report whether or not the test was significant developing this formula:

 t (df) = t value,

 p = p-value

For this particular example, we have found that the t-test is significant as the p-value is less than 0.05.

Results : t(19) = -4.773, p < 0.001

When interpreting we need to use information from both descriptive and inferential statistics in your output.

 1: State the pattern of your data using the means and standard deviations from the first output table.

 Results showed participants made a larger amount of ‘JUMP2’  (mean=2.51 , SD = 1.61) than for JUMP1 (mean = 2.48, SD = 0.159).

2: Report whether or not this difference is significant: A repeated-measures t-test found this difference to be significant,

 t(19) = -4.773, p < 0.001. ·

3: Finally, you need to put this information together to understand and compile what we have found in terms of your hypothesis. therefore, we can reject the null hypothesis and accept the alternative hypothesis.
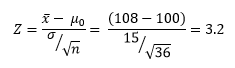
Wilcoxon Rank-Sum test : A Non Parametric Alternative to two Sample T-Test

Statistics, a scientific approach to analyzing numerical data, is employed to discover relationships among the phenomena to describe, predict and control their occurrence.

Statistics helps the researcher to acquire precise, steadfast and dependable findings. Although there are several statistical tests such as ANOVA, independent t-test, etc. to arrive at the right result, one must choose the test according to the type of study.

For instance, if one wants to investigate if the means of two or more groups are different from each other, then he/she must use the ANOVA test. On the other hand, if a researcher wants to test the relationship between categorical variables, the Chi-square test is to be used.

Similarly, for the comparison of means of two independent groups, the two-sample t-test is used. However, if the t-test doesn’t satisfy the requirements for two independent samples, then Wilcoxon Rank-Sum is used as it can offer the two independent samples drawn from populations with an ordinal distribution. This test does not assume known distributions, does not deal with parameters, and hence it is considered as a non-parametric test.

Wilcoxon Rank-Sum test also known as Mann-Whitney U test makes two important assumptions. That is the assumption of independence and equal variance. These assumptions are sufficient for determining if the two populations are different. Additionally, if we assume that the two populations are identical (except for a difference in location), then Wilcoxon Rank-Sum can be utilized as a test of equal means or medians.

Power calculation for Wilcoxon Rank-Sum test

Power is nothing but the probability of rejecting the null hypothesis when it is false. The power calculation for the Wilcoxon Rank-Sum or Mann-Whitney U test is similar to that of the two sample equal-variance t-test except a few modifications are made to the sample size based on the assumed data distribution.

The sample size ni| is equal to ni|= ni/𝑊,

where 𝑊 is known as the Wilcoxon adjustment factor, which is based on the assumed data distribution.

In general, the valid range for the probability of accepting a false null hypothesis is 0 to 1. However, different domains have different standards for setting power.

Sample size conditions 

While solving for sample size, the researcher must choose a condition that describes the constraints either on N1 or N2 or both.

  1. Equal (N1 = N2) – This condition is utilized when a researcher has equal sample sizes in each group. Since both sample sizes are solved at once, no additional sample size parameters are required here.
  2. Include N1, solve for N2 –  This condition is chosen to fix N1 at some value, and then solve only for N2. However, for some values of N1, N2 value that is large enough to acquire the desired power may be absent.
  3. Enter N2, solve for N1–  In case a researcher wants to fix N2 at some value, and then solve only for N1, this condition is used. In this case, too, N1 that is large enough to get the desired power might be absent for some values of N2.
  4. Enter R = N2/N1, solve for N1 & N2<span”> – To choose this condition, one must set a suitable value for the ratio of N2 to N1. This is followed by the determination of required N1 & N2 to obtain the desired power using PASS approach. An equivalent representation of R is
    N2 = R * N1.
  5. Include percentage in group 1, solve for N1 & N2 – Here, the researcher must set a definite value for the percentage of the total sample size in group1. Next, PASS determines the required N1 and N2 with the value of percentage entered to acquire the desired power.
  6. N1 (sample size, group 1) – This condition is used if group allocation = “Enter N1, solve for N2.” Where N1 is the number of individuals sampled from the group 1 population and must be equal or greater than 2. Here a single or a series of values can be entered.
  7. N2 (sample size, group 2) – If group allocation = “Enter N2, solve for N1,” this condition is utilized. Here N2 is the number of individuals sampled from the group 2 population and must be greater or equal to 2. A single or a series of values can be entered in this condition.

The Wilcoxon Rank-Sum test is less sensitive to outliers when compared to that of the two-sample t-test and valid for data from any distribution.

However, it reacts to other differences between the distributions such as differences in shape, especially if the focus is on the differences in location between the two distributions. This is considered as the major disadvantage of the Wilcoxon test. Also, when the assumptions of the two-sample t-test hold, this test is less likely to detect a location shift in comparison with the t-test.

Difference Between One Way ANOVA And Two Way ANOVA

When talking about research in the field of Science or Social science, whether it is Biology, Business, Economics, Psychology, Sociology, or any other subject, the Analysis of Variance (ANOVA) is an important statistical tool for analysing the data. The tool is used to compare and analyse the results of laboratories when more than one factor can be of influence and must be distinguished from random effects. Two folds of the technique lead the comparison; i.e., one way ANOVA and Two-way ANOVA.

ANOVA analysis the statistics on the basis of the hypothesis, either null or an alternate hypothesis. Since a hypothesis is an educated guess of the possible results of the cause-and-effect relationship, it will either result for the cause or against the purpose. The null hypothesis in ANOVA is valid when all the sample means don’t have a significant difference. Similarly, the alternate hypothesis is valid when at least one of the sample mean is different from the rest of the sample means.

As the names indicate of the two-fold techniques, the researcher takes only one factor in one way ANOVA and the researcher investigate two factors simultaneously in two way ANOVA. The former one is a hypothetical test, testing one-factor using variance whereas the later one is a statistical technique studying the influencing variables. However, the independent variables of both the types are proportional to the ways in their names.

One way ANOVA is based on the assumption of normal distribution of the sample population, the ratio level of the dependent variables, the independence of the samples, and the variance of the population. While two way ANOVA is also based on the assumption of normal distribution of the sample population but the measurement of the dependent variable is at a continuous level, unlike the variation in one way ANOVA. The two way ANOVA studies the inter-relationship between the influence of independent variables on dependent variables.

Two way ANOVA is often taken as an extended version of one way ANOVA as the former one has many advantages in the comparison of the later one.

A Quick Guide to Hypothesis Testing in Statistics

This article provides a beginner’s guide to master hypothesis testing in statistics. An example is provided to explain how the guide works.

Hypothesis testing is an important factor for predictive modelling in the field of statistics. Hypothesis testing consists of the following important concepts:

  • Z-value (Z), a statistical term, which is the measure of the standard deviation from the mean value, resulting in the computation of the observed value.
  • P-value, another statistical term associated with the standard normal distribution.
  • Z-table, which shows each P-value associated with each Z-value.
  • Central limit theorem, which is an important theorem in statistics. This theorem states that the mean distribution of the sample size must be normal irrespective of the distribution of the population.
  • Significance level, also called as the alpha level, denotes the accepted cut-off level. In general, a significance level of 5% is acceptable in statistical terms. If the computed probability is lesser than the significance level, it can be concluded that there is no difference between the sample population and the total population size.

Example

For obese patients, the blood-glucose levels are at a mean ( ) of 100 with a standard deviation ( ) of 15. Research has suggested that diet rich in raw corn-starch can raise the glucose levels. A sample size ( ) of 36 patients who were tried with this diet did have an improved glucose level of 108 ( ). Perform a hypothesis test on whether raw corn-starch is beneficial.

Guide to performing hypothesis testing

  1. Determine the type of hypothesis testing (Null or Alternate). For this example, let us choose Null hypothesis.
  2. State the hypothesis for the above example. The population mean is 100.
  3. Set up the significance level. As it is not mentioned for this example, assume it to be 5% (or 0.05).
  4. Calculate the random chance probability, using the following formula:

formulaThe P-value associated with the Z-value of 3.2 is 0.9993. This means that the probability of having a value less than 108 is 0.9993, while the probability of having a value equal to (or more than) 108 is (1-0.9993), which is equal to 0.0007.

  1. As the computed value of 0.0007 is less than the significance level of 0.05, the Null hypothesis test to determine the raw corn-starch effect can be rejected.

Reference
Vidhya, A. (n.d.). Your Guide to Master Hypothesis Testing in Statistics. Retrieved from https://www.analyticsvidhya.com: https://www.analyticsvidhya.com/blog/2015/09/hypothesis-testing-explained/

Pilot Study: All Answers Are Here

These days most of the journals have the online submission system for manuscripts. This has certainly made it easier for the authors to send their papers for the review process. In all good journals, once you have submitted your paper, there is an online tracking system which allows authors to follow the progress of their paper in the review process.

After having submitted the manuscript, the authors go through a journey of stress and anxiety. This is obvious and because of this they keep checking the status of their manuscript. When they get confused or are not able to comprehend the status, they feel all the more perplexed. It also happens at times that the status update does not change for a long time. This also causes them to worry and get tensed. It is not a good idea to contact the journals/editors of the journals very often. If you have not received any notification or update from them for a fortnight, it is acceptable to ask for feedback through a formal mail to the editor. Often, journals take anything between a fortnight to sometimes even a month to get back with their first response to the author.

With some basic doubts and questions answered, authors would be able to have some control on their anxiety as they would know the meaning of a few things they did not know before.

Though there is a lot of subjectivity in each of the journal or publication house but some generalised situations and status may work for all and give you clarity to help you comprehend what different things mean when you verify the status of your manuscript:

1. Manuscript Submitted: This status means that the manuscript has been submitted successfully by the author and there is no other formality pending from the end of the author. From here on it isn’t sent for editing immediately. First the formatting is checked and verified before sending on for further processing.

2. Editor Invited: This status does not apply to all the journals. But those who follow this status, mean that an editor has been assigned for the same and his approval and acceptance is awaited.

3.With Editor: According to this status, the control of your paper has been handed over to an editor and his feedback is awaited on the same. If it clears this stage, it is further sent on for peer review. However, if it gets rejected by the editor here only, it means that it does not live up to the standards of the journal and should not be further forwarded for peer review.

4.Reviewer Invited: Like Step 2, this again is an optional step and not all journals may incorporate this step. After the feedback from the editor, if it is positive then, this status update means that the manuscript has been sent to reviewers and their acceptance is awaited.
There are more status we can know of which we will discuss in the next blog.